
Every time you type a prediction into your phone’s keyboard, you’re feeding data into a system that learns from millions of users. But how do companies train powerful AI models without collecting everyone’s private information? The answer lies in federated learning, a technique that’s quietly reshaping how machine learning works in a privacy-conscious world.
In this article, we’ll break down what federated learning is, how it operates behind the scenes, and why it matters for anyone who cares about data privacy and smarter technology. Whether you’re a developer or simply curious, you’ll walk away with a clear, practical understanding.
Introduction
Federated learning is a machine learning approach that trains a shared model across many devices or servers without moving the raw data into one central location. Instead of sending data to the model, the model travels to the data. Each participating device learns from its local information, then sends only model updates—such as weights or gradients—back to a central server, which combines them into an improved global model.
This matters because data is often sensitive, regulated, or simply too large to move. Hospitals cannot easily share patient records. Banks cannot freely pool customer transactions. Smartphones generate enormous streams of personal text, photos, and usage patterns. Federated learning offers a practical path to build useful models while keeping raw data where it lives. This article explores what federated learning is and how it works with clear, practical guidance you can apply when evaluating or building such systems.
Understanding the fundamentals of federated learning helps you make informed decisions about privacy, infrastructure, and model quality. It is not a magic privacy shield, and it is not the right fit for every problem. But when data is distributed, sensitive, or siloed, federated learning can unlock value that centralized training cannot easily reach.
Key Concepts
Before diving into mechanics, it helps to understand a few core ideas that appear in almost every federated learning system.
- Local training: Each client—a phone, hospital server, or branch office—trains a copy of the global model on its own data for a small number of steps.
- Model updates: Instead of sharing data, clients share the changes to the model, such as updated weights or gradients.
- Aggregation: A central server combines updates from many clients into a new global model, often using an algorithm called Federated Averaging (FedAvg).
- Communication rounds: Federated learning typically proceeds in rounds. Clients train, send updates, the server aggregates, and the improved model is sent back for the next round.
- Non-IID data: Unlike centralized datasets, client data is often not independently and identically distributed. One phone may be used mostly for Spanish text; another mostly for photos. This heterogeneity is a central challenge.
- Privacy mechanisms: Techniques like secure aggregation, differential privacy, and gradient compression reduce the risk that updates leak sensitive information.
- Client selection: In large networks, only a subset of clients participate in each round to save bandwidth and battery. How you choose them affects fairness and convergence.
These concepts form the vocabulary of federated learning. If you can explain local training, aggregation, and non-IID data, you already understand the heart of the approach.
Deep Dive
Federated learning works through a repeating cycle. First, the server initializes a global model and selects a set of clients. Each selected client downloads the current model, trains it locally on its private data, and computes an update. The client sends that update—not the data—back to the server. The server aggregates the updates, typically by averaging them weighted by the number of local examples. The new global model is then distributed for the next round. This loop continues until the model converges or a stopping criterion is met.
There are different flavors of federated learning. In cross-device settings, millions of phones or IoT devices participate, often with unreliable connectivity and limited battery. In cross-silo settings, a smaller number of organizations—hospitals, banks, or research labs—collaborate, each with substantial and reliable compute. Cross-silo systems can afford more communication and stronger privacy guarantees. Cross-device systems must be extremely efficient and fault-tolerant.
The main technical challenges are communication efficiency, statistical heterogeneity, and privacy. Communication is often the bottleneck because uploading large model updates over slow networks is expensive. Researchers address this with compression, quantization, and by increasing the amount of local computation between rounds. Statistical heterogeneity means a simple average of client updates can perform poorly; solutions include personalized models, meta-learning, and robust aggregation. Privacy is nuanced: sharing gradients can still leak information. Secure aggregation ensures the server only sees the sum of updates, while differential privacy adds noise to protect individual contributions.
Federated learning also has practical limitations. It requires many participating clients to be useful. It can be slower to converge than centralized training. It demands robust infrastructure for orchestration, versioning, and monitoring. And it is not automatically private—privacy must be engineered deliberately. Understanding these trade-offs is essential before committing to a federated approach.
Best Practices
If you are considering federated learning, these practices will help you avoid common pitfalls and build systems that are both effective and responsible.
- Start with a clear privacy goal. Decide whether you need secure aggregation, differential privacy, or both. Document what threats you are defending against.
- Benchmark against centralized training. Establish how much accuracy you lose by not centralizing data. Sometimes the gap is small; sometimes it is unacceptable.
- Design for heterogeneity. Assume client data differs widely. Use techniques like personalized layers, client clustering, or robust aggregation instead of naive averaging.
- Minimize communication. Increase local computation, compress updates, and select clients strategically to reduce bandwidth and latency.
- Build for failure. Clients drop out, networks fail, and devices sleep. Your orchestration layer must handle partial participation gracefully.
- Monitor for drift and bias. Track model performance across client groups. Federated models can underperform for underrepresented clients.
- Be transparent with users. Explain what data stays local, what updates are shared, and how privacy is protected. Trust is a technical requirement, not just a legal one.
- Invest in tooling. Frameworks like TensorFlow Federated, PySyft, and Flower can accelerate development, but you still need logging, versioning, and evaluation pipelines.
Reliable information and consistent habits lead to better long-term outcomes. That is as true for federated learning operations as for any other engineering discipline. Consistent monitoring, regular privacy audits, and iterative improvement will outperform one-time heroics.
Step-by-Step Guide
Use this sequence to move from understanding to implementation. Each step builds on the previous one, and skipping steps usually leads to wasted effort.
Step 1: Understand the fundamentals
Before writing code or selecting a framework, make sure you can explain federated learning in plain language. Know the difference between local training, model updates, and aggregation. Understand why non-IID data is hard and why communication is often the bottleneck. Read at least one foundational paper, such as the original Federated Averaging work, and one practical survey. If you cannot describe the round-based training loop from memory, revisit the Key Concepts section above.
Step 2: Assess your starting point
Evaluate your current data landscape. Where does the data live? How many clients or silos are involved? What are the legal and regulatory constraints? Do you already have a centralized model, and what accuracy does it achieve? Identify the gap you want federated learning to close. If your data is already centralized and not sensitive, federated learning may add complexity without benefit. Be honest about infrastructure: do you have reliable orchestration, secure communication, and monitoring in place?
Step 3: Set clear goals
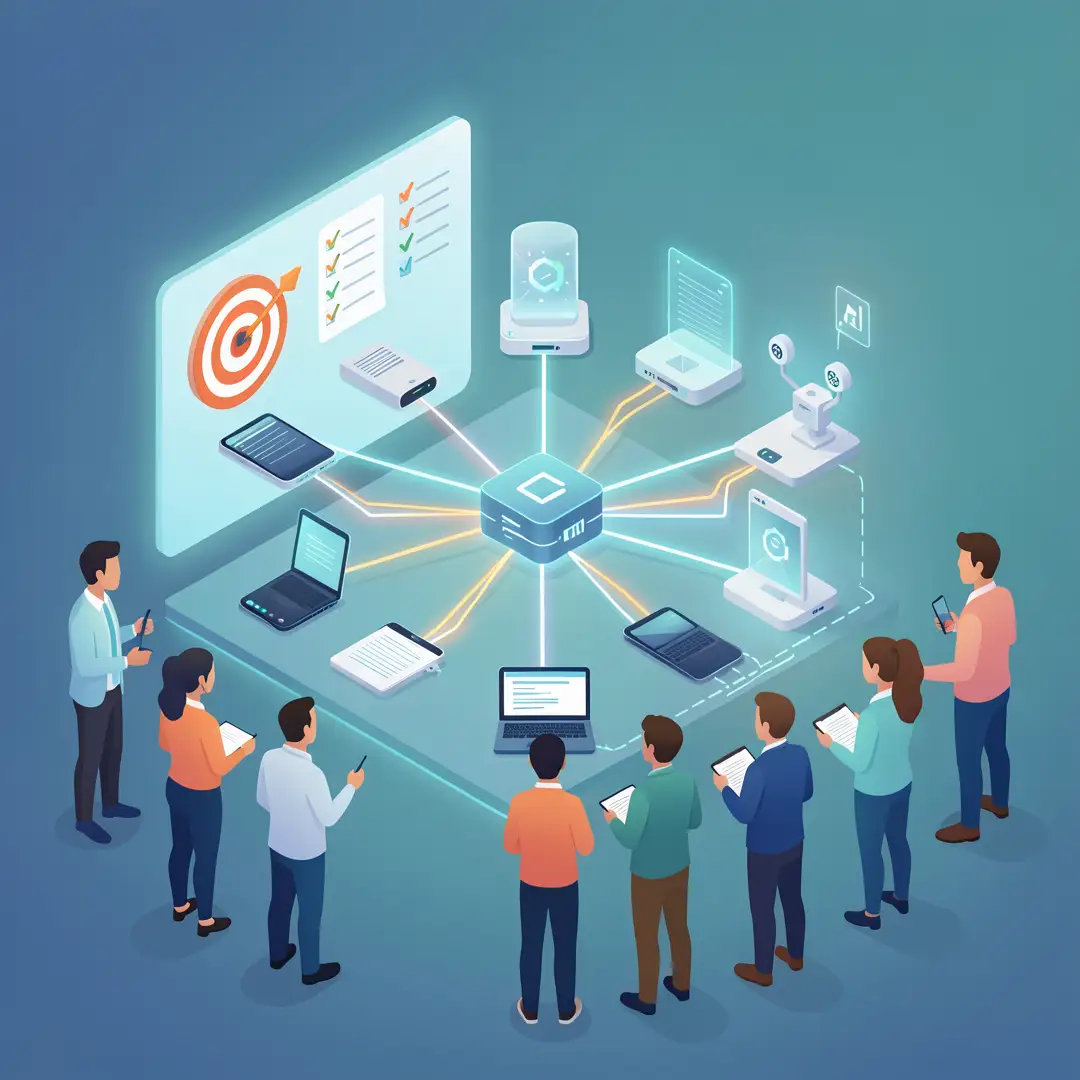
Define what success looks like in measurable terms. Examples include achieving 95% of centralized model accuracy, reducing data transfer by 80%, or enabling collaboration across three hospitals without sharing patient records. Set a timeline and a minimum viable experiment. Separate must-have goals from nice-to-have goals. Write them down and share them with stakeholders, because federated learning projects often involve legal, security, and engineering teams with different priorities.
Step 4: Gather necessary resources
Assemble the people, tools, and data access you need. On the people side, you typically need machine learning engineers, a privacy or security specialist, and a project manager. On the tooling side, choose a framework that matches your setting—cross-device or cross-silo—and supports the privacy mechanisms you require. Confirm that you have permission to use each client’s data for local training. Prepare simulation environments so you can test before deploying to real devices or organizations.
Step 5: Apply the core methods
Implement the federated training loop. Start with a simple Federated Averaging setup in simulation. Train a baseline model centrally, then compare it to the federated version using the same evaluation data. Introduce privacy mechanisms one at a time: first secure aggregation, then differential privacy if needed. Test with realistic client heterogeneity and partial participation. Measure accuracy, communication cost, and training time. Iterate on hyperparameters such as local epochs, batch size, and client sampling rate. Keep the system as simple as possible until it works, then add complexity only where measurements justify it.
Step 6: Monitor your progress
Once deployed, monitor continuously. Track model accuracy over rounds, participation rates, communication volume, and privacy budget consumption. Watch for client drift, where some clients consistently perform worse. Set up alerts for aggregation failures, anomalous updates, and sudden drops in participation. Review logs regularly and conduct periodic privacy audits. Use what you learn to refine client selection, aggregation strategy, and privacy settings. Federated learning is an ongoing operation, not a one-time deployment.
FAQ
What should I know about What Is Federated Learning and How Does It Work?
Federated learning trains a shared model across distributed data without moving raw data to a central server. The key idea is simple: clients train locally and share only model updates. What surprises many people is that federated learning is not automatically private. Updates can leak information, so secure aggregation and differential privacy are often necessary. It also is not always better than centralized training; it trades some accuracy and speed for privacy and reduced data movement. Understanding these trade-offs helps you decide whether it fits your problem.
Who is this guide for?
This guide is for readers who want a clear, practical introduction to federated learning. That includes product managers evaluating privacy-preserving machine learning, engineers building distributed systems, data protection officers assessing risk, and students or researchers entering the field. You do not need deep expertise in cryptography or distributed systems, but some familiarity with machine learning basics—training, models, and evaluation—will help you get the most from it.
Conclusion
Federated learning is a powerful approach for training models on data that cannot or should not be centralized. It works by bringing the model to the data, training locally, and aggregating updates in a central server. Its strengths are.
You now have a solid foundation for What Is Federated Learning and How Does It Work. Apply the best practices above and revisit this guide as your needs evolve.